DOCFLOW
Intelligent Document Processing
Turn documents into structured intelligence.
Stop paying people to retype invoices and contracts — extract the data, check it, and push it straight into the systems that need it.
- OCR
- Layout models
- Classification
- Extraction
- Validation rules
- ERP integration
A processing pipeline that reads documents, classifies them, extracts structured fields with confidence, validates against business rules, and routes only the uncertain ones to a human.
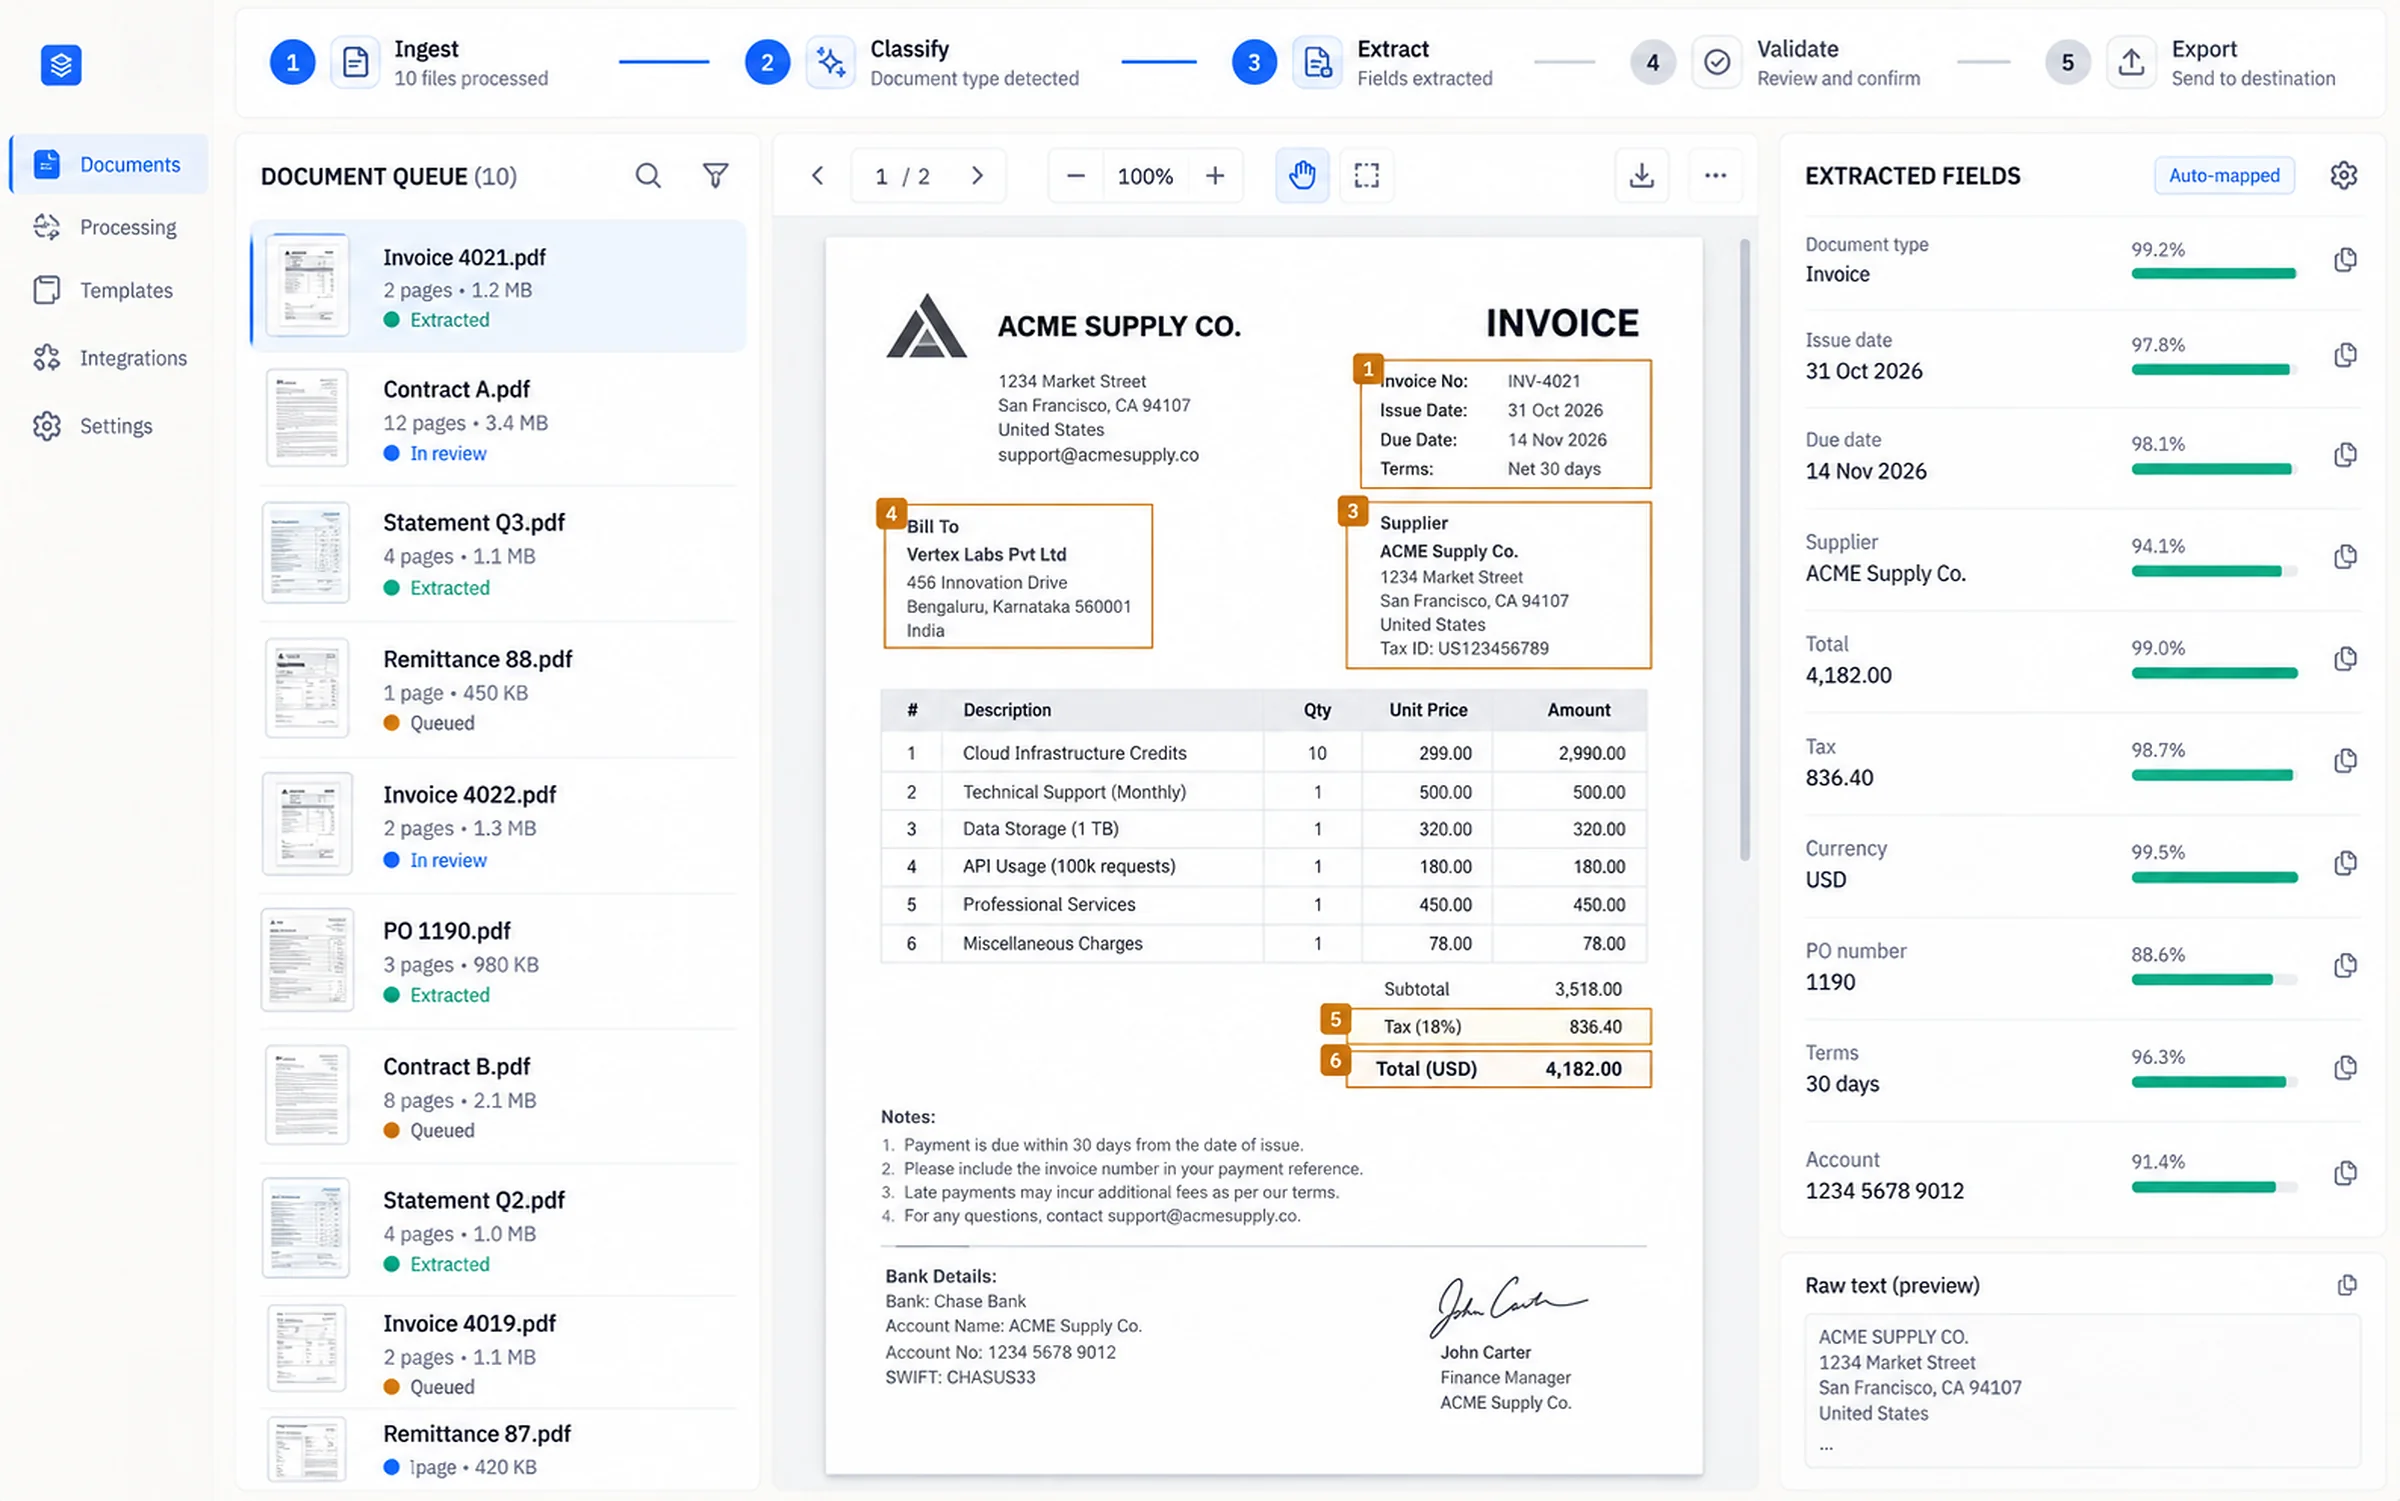
What the product is built around.
The measure of success is straight-through processing rate, not model accuracy in isolation. A pipeline that extracts perfectly but cannot prove it is still a pipeline someone has to check.
Confidence decides the route
Per-field confidence plus validation outcome determines whether a document posts automatically or goes to review. There is no silent middle path.
Every field is traceable
Extracted values link to the page region they came from, so a reviewer verifies in a glance instead of reading the whole document.
Rules, not templates
Validation is declarative business logic. A new supplier layout is handled by the model; a new business rule is a config change.
What makes this hard.
Every finance and operations team runs a hidden data-entry department. Invoices arrive as PDFs and scans, someone opens each one, types eight fields into an ERP, spots the ones that do not match a purchase order, and emails a supplier. It is slow, it is expensive, and the error rate is invisible until an audit.
- 01
Documents arrive in a dozen formats and half of them are scans of printouts
- 02
Field extraction by hand costs hours per day and introduces silent typos
- 03
Template-based tools break the moment a supplier changes their layout
- 04
Generic AI extraction returns plausible numbers with no way to check them
- 05
Exceptions have no workflow, so they live in an inbox until someone chases
What the system does.
DOCFLOW treats extraction as a pipeline with a confidence gate at the end rather than a single model call. Documents are OCR'd, classified by type, and read by layout-aware extraction that returns each field with the region of the page it came from. Business rules validate the result against existing records, and only documents that fail a rule or fall below the confidence threshold reach a human — who sees the field highlighted on the page rather than hunting for it.
Layout-aware extraction handles new formats without a per-supplier template
Every field carries a confidence score and a link to its location on the page
Validation rules check totals, tax and purchase-order matches before anything posts
Only low-confidence or rule-failing documents reach a reviewer
Approved output posts to ERP, CRM or database with an idempotency key
DOCFLOW, as working interface.
Rendered UI, not a mockup — real tables, charts, filters and states. Try ⌘K for the command palette.
Documents (30D)
184,204
Straight-through
87.2%
Extraction accuracy
98.2%
Review queue
18
Processing pipeline — INV-104821.pdf
Nordvik Supply · 2 pages · received 09:41 via email intakeExtracted fields
- Supplier
- Nordvik Supply AB
- Invoice no.
- INV-104821
- PO reference
- PO-88412
- Invoice date
- 2026-09-18
- Due date
- 2026-10-18
- Net
- €11,424.00
- VAT (25%)
- €2,856.00
- Total
- €14,280.00
- Currency
- EUR
- Mean confidence
- 0.96
Line items — extracted and matched
| # | Description | Qty | Unit | Total | PO match | Confidence | Status |
|---|---|---|---|---|---|---|---|
| 1 | Aluminium bracket, 40mm | 240 | €8.40 | €2,016.00 | exact | 0.99 | Matched |
| 2 | Steel fastener set M6 | 1,200 | €0.62 | €744.00 | exact | 0.98 | Matched |
| 3 | Powder coating service | 1 | €1,840.00 | €1,840.00 | exact | 0.97 | Matched |
| 4 | Rubber gasket, 60mm ID | 480 | €2.10 | €1,008.00 | exact | 0.99 | Matched |
| 5 | Assembly labour, hours | 64 | €48.00 | €3,072.00 | exact | 0.96 | Matched |
| 6 | Expedited freight surcharge | 1 | €412.00 | €412.00 | not on PO | 0.61 | Variance |
| 7 | Packaging materials | 80 | €3.40 | €272.00 | exact | 0.98 | Matched |
| 8 | Quality inspection fee | 1 | €2,060.00 | €2,060.00 | exact | 0.95 | Matched |
7 of 8 lines matched the purchase order exactly · line 6 routed to review with the page region highlighted
Validation rules
declarative · v12- Line items sum to netpass
- VAT matches jurisdiction ratepass
- Net + VAT equals totalpass
- Currency matches supplier recordpass
- Duplicate invoice checkpass
- Payment terms within policypass
- All lines present on POfail · 1 line
Document mix
- Supplier invoices60.9%
- Receipts & expenses20.7%
- Contracts9.8%
- Bank statements6.0%
- Other2.7%
Confidence distribution
field levelStraight-through processing rate
90DReview queue
- INV-104821 · Nordvik SupplyLine 6 not on PO · €412 variance0.61
- INV-104818 · Akselos TradeSupplier not in master datano match
- CTR-2841 · MSA renewalClause deviation from template0.72
- INV-104802 · Meridian GoodsScan quality low · 2 fields uncertain0.68
- RCP-88120 · expense claimHandwritten total · OCR uncertain0.54
- STM-4412 · bank statementPage 3 rotated · reprocessed0.91
Validation rule
versioned separately from the model# Rules are declarative and versioned, so a policy change# never requires retraining or redeploying the extractor.rules: - id: lines_sum_to_net assert: sum(line_items.total) == net tolerance: 0.01 on_fail: review - id: vat_matches_jurisdiction assert: vat == net * rate(supplier.country) tolerance: 0.01 on_fail: review - id: all_lines_on_po assert: every(line_items, l => l.po_match != null) on_fail: review # never auto-post an unmatched line - id: duplicate_invoice assert: not exists(invoice_no, supplier_id) on_fail: block # hard stop, not a reviewthresholds: field_confidence: 0.85 straight_through: all_rules_pass and min(field_confidence) >= 0.85Document audit trail
append-only- 09:41:58systemqueued_reviewINV-104821 · rule all_lines_on_po failed
- 09:41:54validator:v12validated6 of 7 rules passed
- 09:41:49extractor:v4.2extracted14 fields · 8 line items · mean 0.96
- 09:41:44classifier:v3classifiedsupplier_invoice · EU · 0.99
- 09:41:41ocr:v2.8ocr_complete2 pages · word conf 0.98
- 09:41:38intake:emailreceivedap@demo · 184 KB · hash 7c2e41
Interface states
UI statesNo documents yet
Connect an email intake, SFTP drop or upload a document to start processing.
Upload documentEmpty stateCannot extract from this document
OCR returned 54% word confidence on a handwritten total. Extraction was not attempted rather than producing an unreliable figure — the document is queued for manual entry.
How it is put together.
The confidence gate is the whole product. Extraction quality matters, but what makes it deployable is knowing which results can be trusted without a human.
- 01
Intake
Email, upload, SFTP and API with deduplication by content hash.
- Queue
- Content hashing
- Virus scanning
- 02
OCR
Layout-preserving text recognition with per-word confidence and deskewing.
- OCR engine
- Image preprocessing
- Table detection
- 03
Classification
Document type and regional format detection with a confidence score.
- Classifier
- Few-shot prompting
- 04
Extraction
Layout-aware field and line-item extraction with page-region provenance.
- Layout models
- Vision LLM
- Schema validation
- 05
Validation
Declarative business rules over the extracted structure, versioned independently.
- Rules engine
- Fixed-point maths
- Master-data lookup
- 06
Review & Posting
Human review of uncertain fields, then idempotent posting to systems of record.
- Review UI
- Idempotency keys
- ERP connectors
What the product does.
The capability set the demonstration is built around.
Ingestion
Email, upload, SFTP and API intake with deduplication and format detection.
OCR
Layout-preserving OCR with per-word confidence and skew and rotation correction.
Classification
Document type detection across invoices, contracts, receipts and statements.
Extraction
Layout-aware field and line-item extraction with page-region provenance.
Validation
Declarative rules for totals, tax, currency and purchase-order matching.
Human review
Side-by-side document and fields with the uncertain value highlighted in place.
Integrations
Idempotent posting to ERP, CRM, accounting systems and data warehouses.
Audit trail
Every extraction, correction and post recorded with the model version used.
Challenges, and the MaatX approach.
The problems that actually decide whether a system like this survives production — and how we address each one.
Extraction that is 95% accurate still needs 100% of documents checked
Per-field confidence plus rule outcomes decide the route. Documents where every field clears the threshold and every rule passes post automatically; the rest go to review. The metric that matters is straight-through rate, not raw accuracy.
A reviewer cannot trust a number they have to hunt for
Extraction returns the page region for each field. The review UI shows the document with the uncertain value highlighted in place, which turns verification into a glance rather than a read.
Template-based extraction breaks when a supplier changes their layout
Extraction is layout-aware rather than coordinate-based, so a new format is handled without onboarding a template. Only genuinely new document types need attention.
Reprocessing a document must not post it twice
Posting carries an idempotency key derived from the document hash and target system. A reprocess updates the extraction record but cannot create a second ERP entry.
Model upgrades silently change what gets auto-posted
Every extraction records the model version that produced it, and a new version runs in shadow against a labelled set before it takes traffic. Straight-through rate is compared per version.
A bad scan produces a plausible wrong number
OCR word confidence gates the pipeline. Below threshold, extraction is not attempted and the document routes to manual entry — a missing value is recoverable, a confidently wrong one is not.
The stack behind it.
Intake
- Python
- Queues
- Email intake
- SFTP drop
- Upload API
- Content hashing
- Virus scanning
OCR & image pipeline
- OCR engine
- Image preprocessing
- Deskew and rotation correction
- Per-word confidence
- Table detection
- Page segmentation
Classification & extraction
- Classifier
- Few-shot prompting
- Layout models
- Vision LLM
- Line-item extraction
- Page-region provenance
- Schema validation
Validation rules
- Rules engine
- Declarative rule config
- Fixed-point arithmetic
- Master-data lookup
- Purchase-order matching
- Duplicate-invoice checks
Confidence routing & review
- Per-field confidence thresholds
- Straight-through gating
- Review queue
- In-place field highlighting
- PDF rendering
- Next.js
- React
Posting & integrations
- Node.js
- TypeScript
- PostgreSQL
- ERP connectors
- Idempotency keys
- Webhooks
- Warehouse sinks
Model operations & audit
- Model version pinning
- Shadow evaluation
- Labelled eval sets
- Straight-through rate tracking
- Reviewer-correction capture
- Per-document audit trail
How it grows with the business.
The same system at three stages. Most products should not start at the third — but the architecture should not have to be thrown away to get there.
One document type, one target system, with a human reviewing everything to establish a baseline.
- Single document type (supplier invoices)
- Upload and email intake
- Extraction with confidence scores
- All documents reviewed to measure real accuracy
Multiple document types with automatic posting for everything that clears the gate.
- Classification across document types
- Declarative validation rules with master-data lookup
- Straight-through posting above threshold
- Review queue with in-place field highlighting
Multi-entity, multi-region processing with the controls an audit requires.
- Multi-entity routing and approval hierarchies
- Regional data residency and retention policy
- Full audit trail with model version per extraction
- Shadow evaluation before any model upgrade takes traffic
Where it could go next.
Directions this system would extend into.
- 01
Contract intelligence with clause comparison against a standard template
- 02
Supplier-specific learning from reviewer corrections
- 03
Three-way matching across purchase order, receipt and invoice
- 04
Anomaly detection for duplicate and fraudulent invoices
- 05
Document-level Q&A over the processed archive
Processing documents where extraction has to be validated before anything reaches your ERP?
We built DOCFLOW to work through exactly this. Tell us where you are and we will tell you what we would do differently for your constraints.