AI systems beyond
the model.
The model is one component of eight. Most of what decides whether an AI system reaches production lives in the retrieval, the permissions and the evaluation nobody demos.
Eight layers, not one.
A retriever that returns the wrong passage, a context window that leaks a document, a tool call that runs twice. None of those are model problems.
- 01
Ingestion
Parsing and chunking that preserves document structure, so a table stays a table.
- Parsers
- Chunking
- OCR
- 02
Retrieval
Hybrid dense and lexical search with reranking, because embeddings alone miss exact terms.
- Vector search
- BM25
- Rerankers
- 03
Context
Assembled under an entitlement filter, so an answer can only use what the asker may see.
- Entitlements
- Token budget
- 04
Model
One component behind a contract, with routing and a fallback when a provider degrades.
- OpenAI
- Anthropic
- Routing
- 05
Tools
Typed tools with scoped capabilities and side effects that are safe to retry.
- JSON Schema
- MCP
- Idempotency
- 06
Guardrails
Approval gates on anything that spends money, sends a message or changes a record.
- Policy as config
- Human-in-the-loop
- 07
Evaluation
Labelled suites and groundedness scoring that run before a prompt change ships.
- Eval harness
- Regression gates
- 08
Observability
Replayable traces with cost and latency attributed per step and per tenant.
- Tracing
- Cost attribution
What we build with AI.
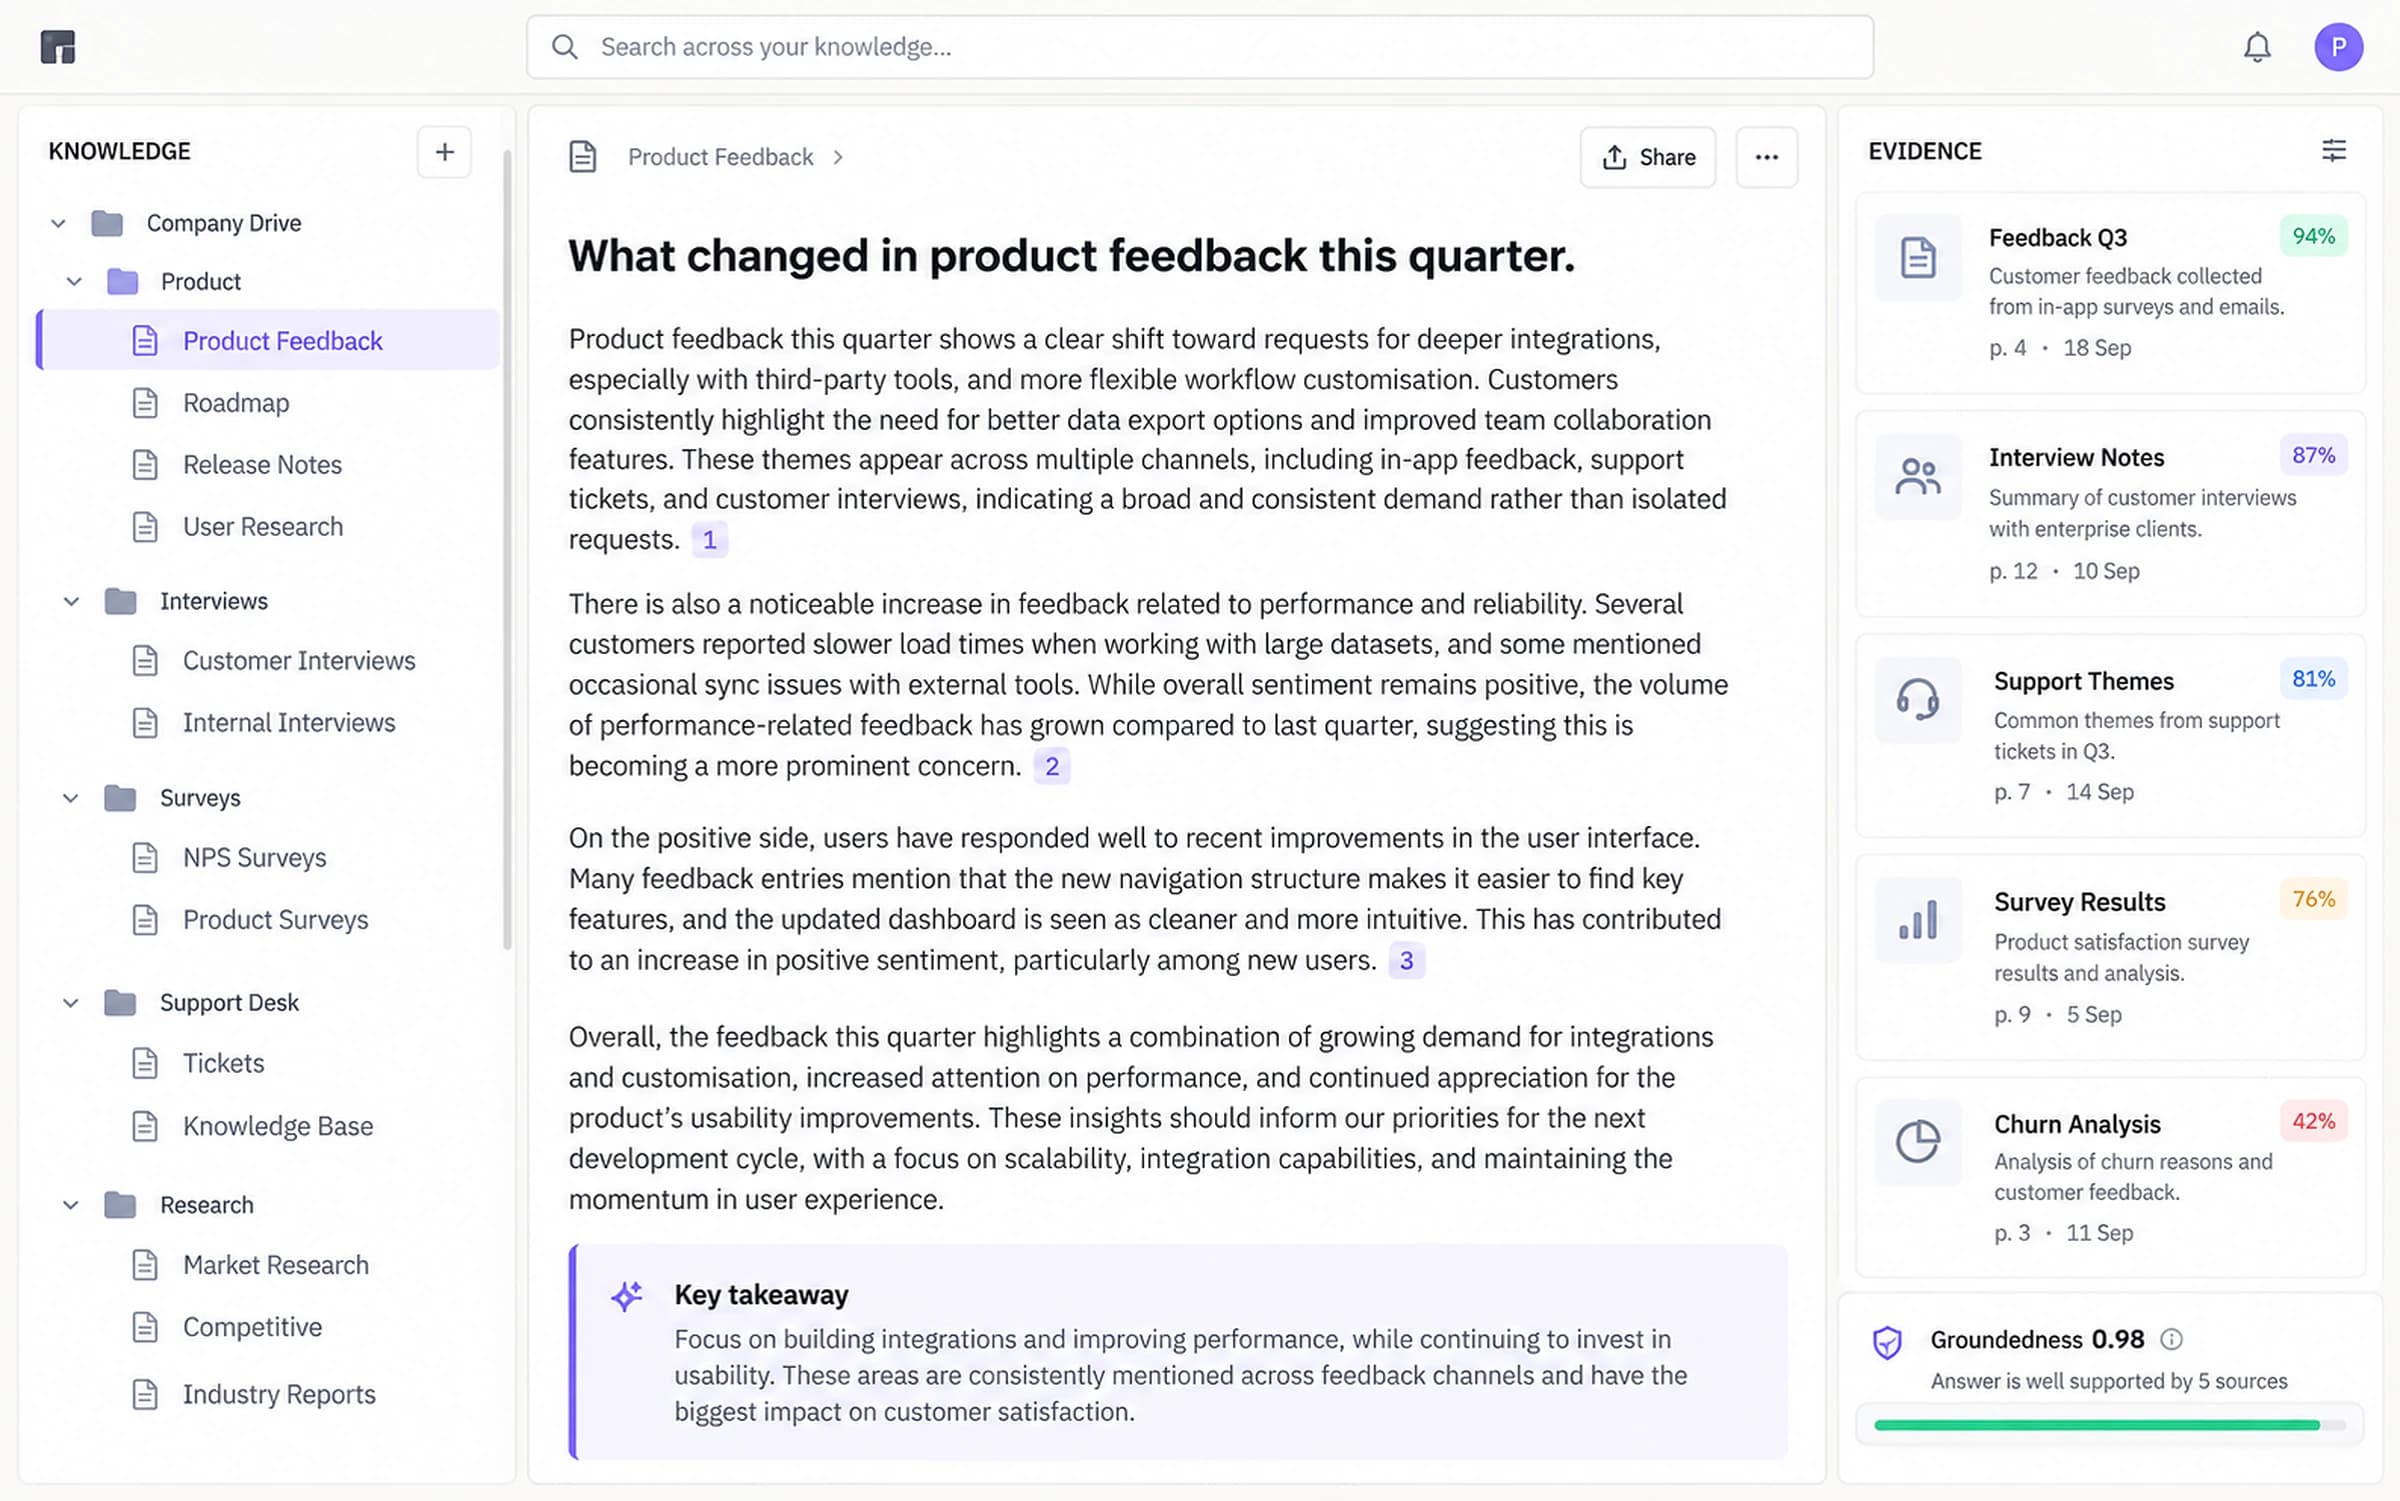
Each of these fails in a different way, which is why each is engineered as its own system rather than as one assistant with a different prompt.
Also in scope
Enterprise search
One index across the systems a company already runs.
Multi-agent systems
Several agents with scoped roles and a shared protocol.
Model routing
Cheapest model the evaluation shows is good enough.
Knowledge graphs
Entities and relations, so retrieval can reason over structure.
Sales intelligence
Public and internal signals resolved to one account view.
Where AI systems actually fail.
These are the problems we design for first, because retrofitting them is expensive.
Retrieval returns the wrong passage, confidently
Hybrid retrieval with reranking, and answers that cite the span they used — so a wrong source is visible on the page instead of buried inside fluent prose.
The context window leaks permissions
Entitlements are applied while context is assembled, not after generation. An answer cannot quote a document the person asking is not allowed to open.
An agent runs its side effect twice
Every tool call carries an idempotency key and moves through an explicit state machine, so a retry cannot double-charge a card or send a second message.
Quality regresses on a prompt nobody tested
A labelled evaluation suite and groundedness scoring run before release, so a regression fails the build rather than reaching a customer first.
Cost scales faster than usage
Token spend is attributed per step and per tenant, which is what makes it safe to route a request to a cheaper model where evaluation shows no loss in quality.
Building something with AI?
Bring us the system, the product or the problem. We’ll help define the architecture and the path to production.